
PhD, AI safety and alignment
ELLIS Institute Tübingen and MPI for Intelligent Systems · ELLIS PhD Program
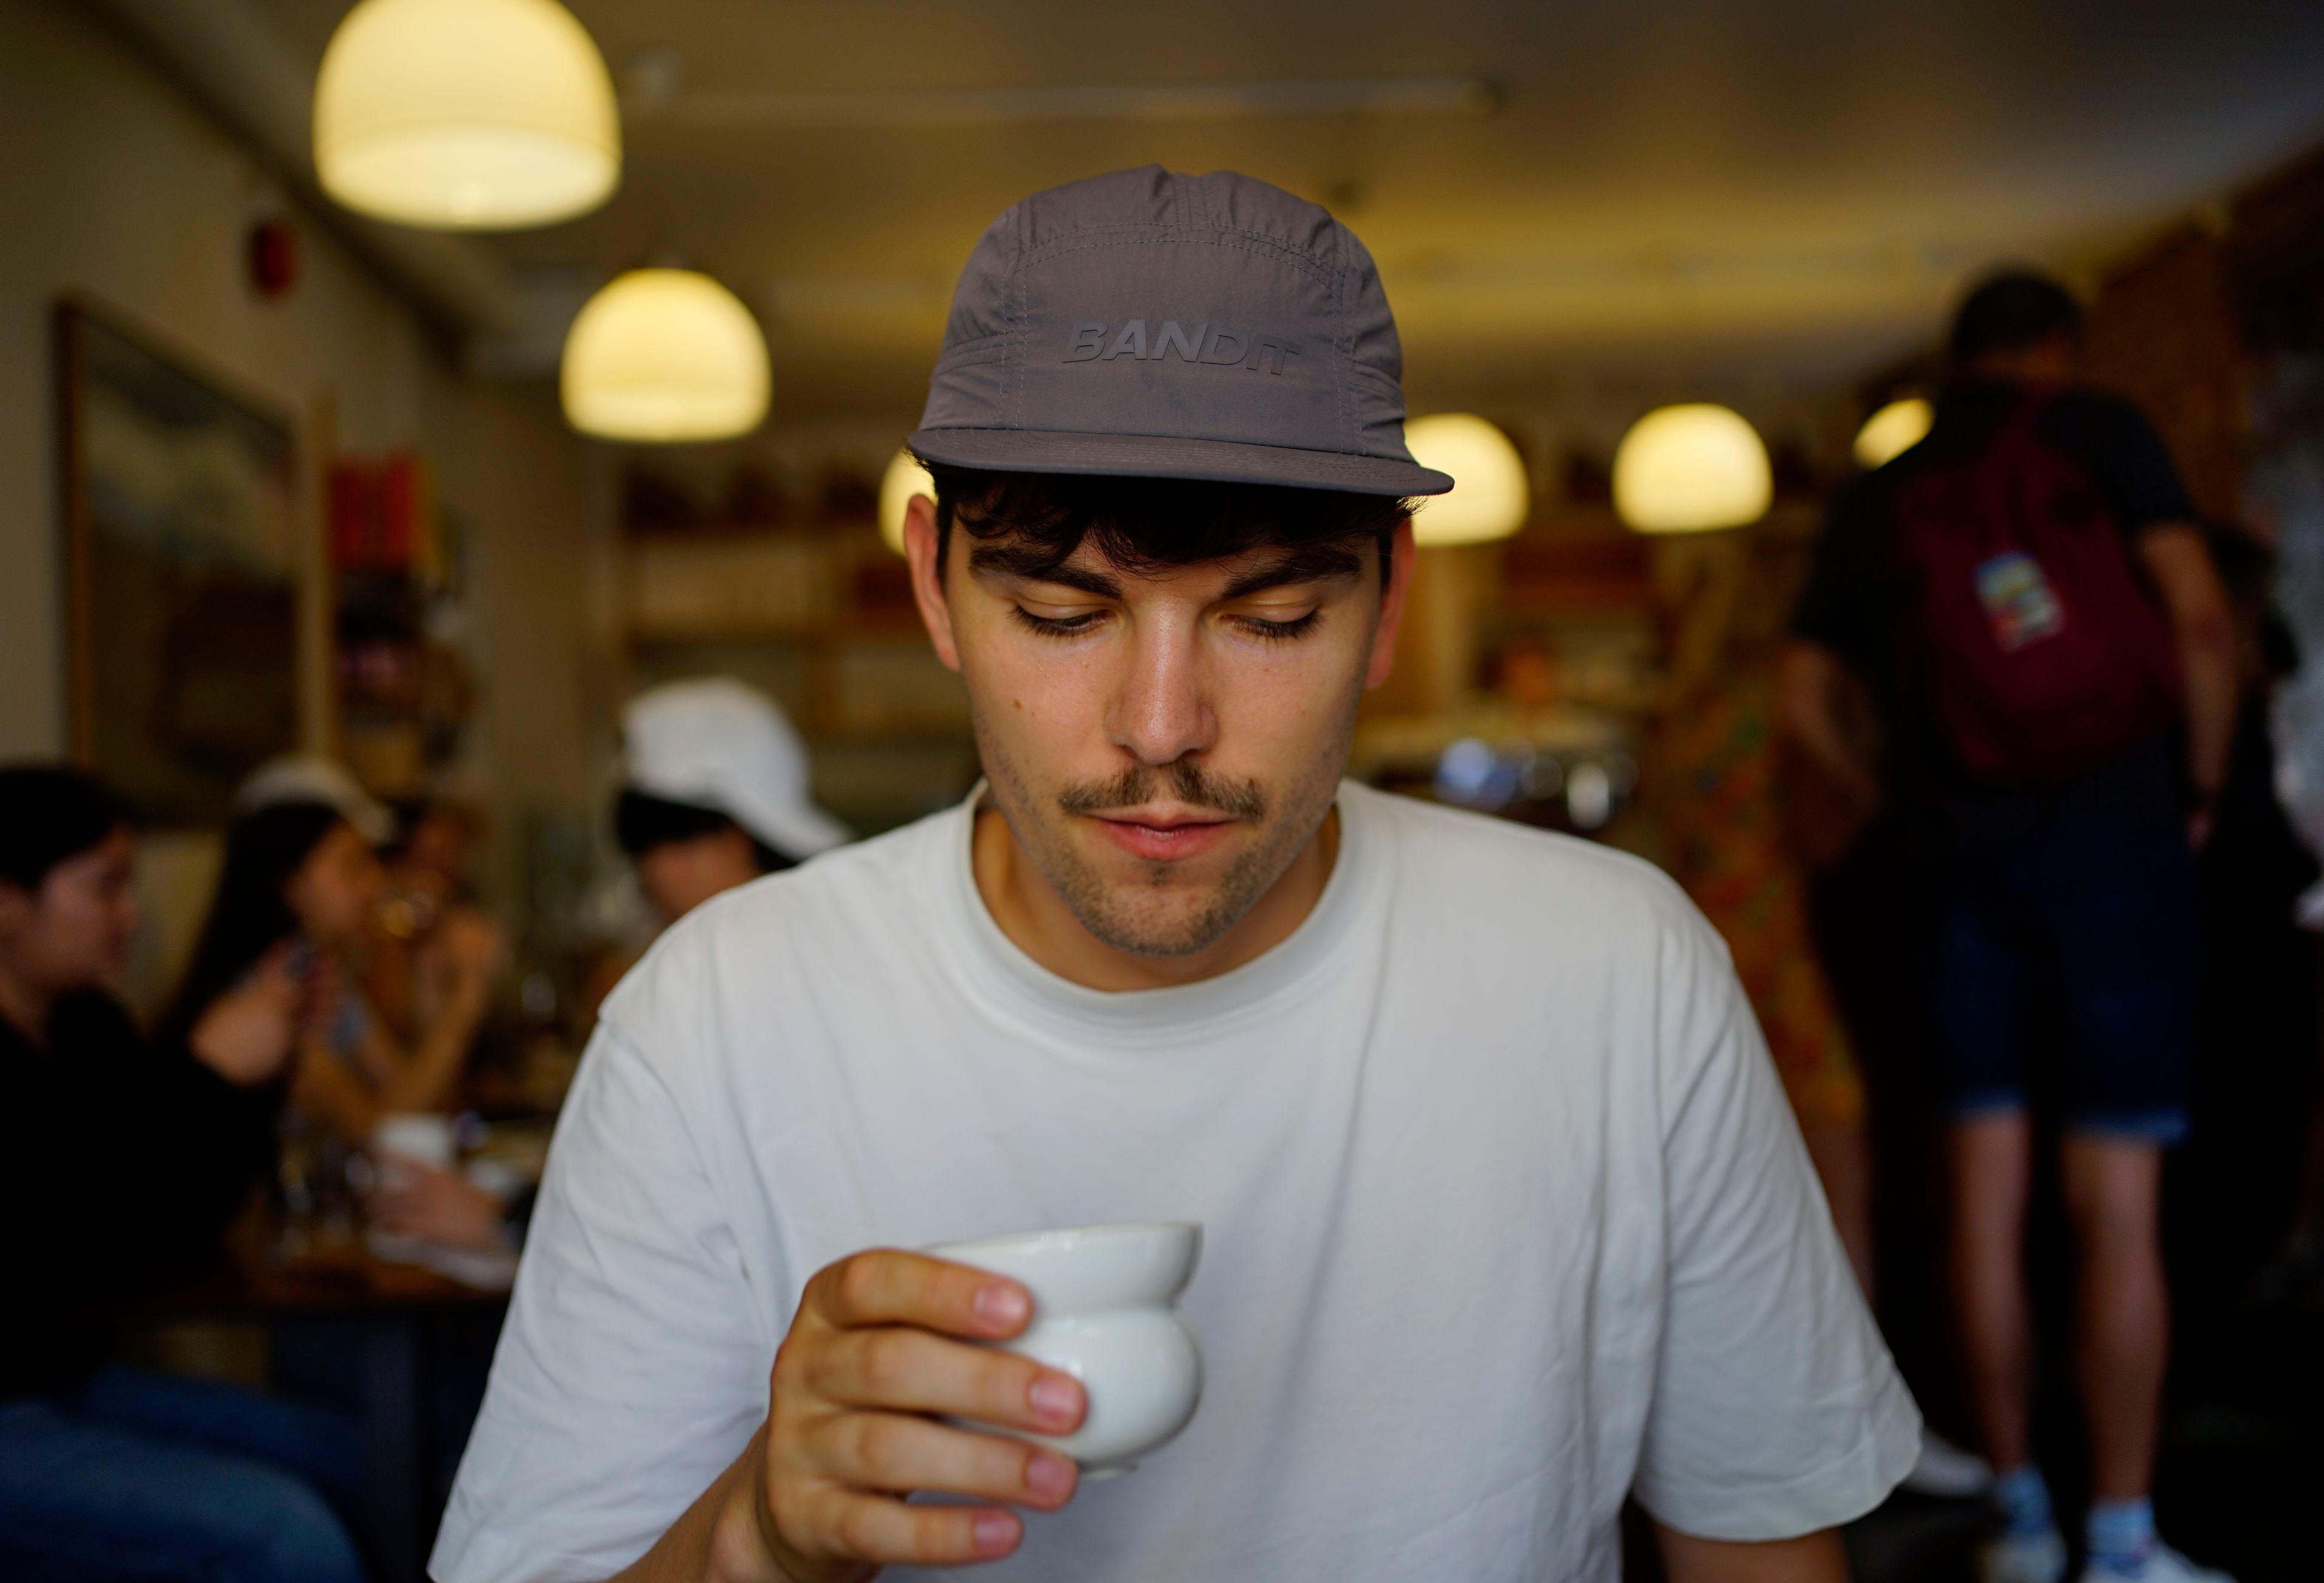
I want to know why language models fail.
I'm a PhD student at the ELLIS Institute Tübingen and the MPI for Intelligent Systems, working with Maksym Andriushchenko, and with Yonatan Belinkov as co-supervisor through the ELLIS program. Mostly, I am interested in when and why current models and agentic systems misbehave. I try to find out by using interpretability and hope to make the answers actually useful.
PhD at the intersection of interpretability and AI safety, starting November 2026.
With Sanghwan Kim, Cordelia Schmid, Zeynep Akata.
ICML 2026, Mechanistic Interpretability Workshop
With Ian Colbert, Giuseppe Franco, Jinjie Zhang, Rayan Saab.
TMLR, December 2025 · arXiv 2409.17092
With Akshaj Kumar Veldanda, Shailja Thakur, Hammond Pearce, Benjamin Tan, Ramesh Karri, Siddharth Garg.
NeurIPS 2023, R0-FoMo Workshop · arXiv 2310.05135
ELLIS Institute Tübingen and MPI for Intelligent Systems · ELLIS PhD Program
Konrad Zuse School of Excellence in Reliable AI, 2024 cohort
Center for Cybersecurity. Fairness in large language models, and security in code generation
Full scholarship, awarded to the top one percent of German students
Thesis on quantization for neural networks on RRAM crossbars. Erasmus semester at AGH Kraków
I'm curious about lots of things, passionate about some, and deep in a few. I like things that require precision and build over time.
Outside the lab I run marathons, make coffee more carefully than necessary, and ride up mountains. Happy to talk about any of it.